Picture a huge library. Multiple floors. Millions of books. No catalog. No computers. The only order? The date each book was donated.
You need one novel. Published in 2015. But you can't remember the author's name.
So you walk every aisle. Check every shelf. Pick up every book.
That's a full collection scan. And that's exactly what your MongoDB database does when you query a field with no index.
An index is the card catalog that library never had. It's a separate, sorted structure that maps values to where the data lives on disk. Instead of reading a million documents to find alex@example.com, the database checks the index, grabs the pointer, and returns the doc in milliseconds.
This guide is about mastering that. We'll start simple, then get into the stuff that makes production queries fast. Most examples are MongoDB, but I'll call out where SQL and Postgres differ so the ideas carry over.
Read article on Before Adding a Vector Database
What Exactly Is a Database Index?
An index is a small, sorted copy of part of your data. Not the whole document. Just a signpost.
Say you have a users collection:
json
{
  "_id": ObjectId("..."),
  "name": "Alex Johnson",
  "email": "alex@example.com",
  "age": 34,
  "city": "New York",
  "profession": "Software Engineer"
}
Make an index on email, and the database builds something like this:
email (Index Key) | Location Pointer |
|---|---|
abby@example.com | Record Location 405 |
alex@example.com | Record Location 102 |
zack@example.com | Record Location 890 |
It stays sorted. And because it's sorted, the database can use binary search to jump straight to alex@example.com. No scanning every entry.
Here's the thing: this works the same in Postgres, MySQL, and MongoDB. A B-Tree index in InnoDB does the same job as a B-Tree index in MongoDB's WiredTiger. Different code. Same idea.
Read article on: "How to Design a MongoDB Schema for Optimal Performance"
Why Indexes Make Queries Faster
This isn't a small speedup. It's a totally different way of working.
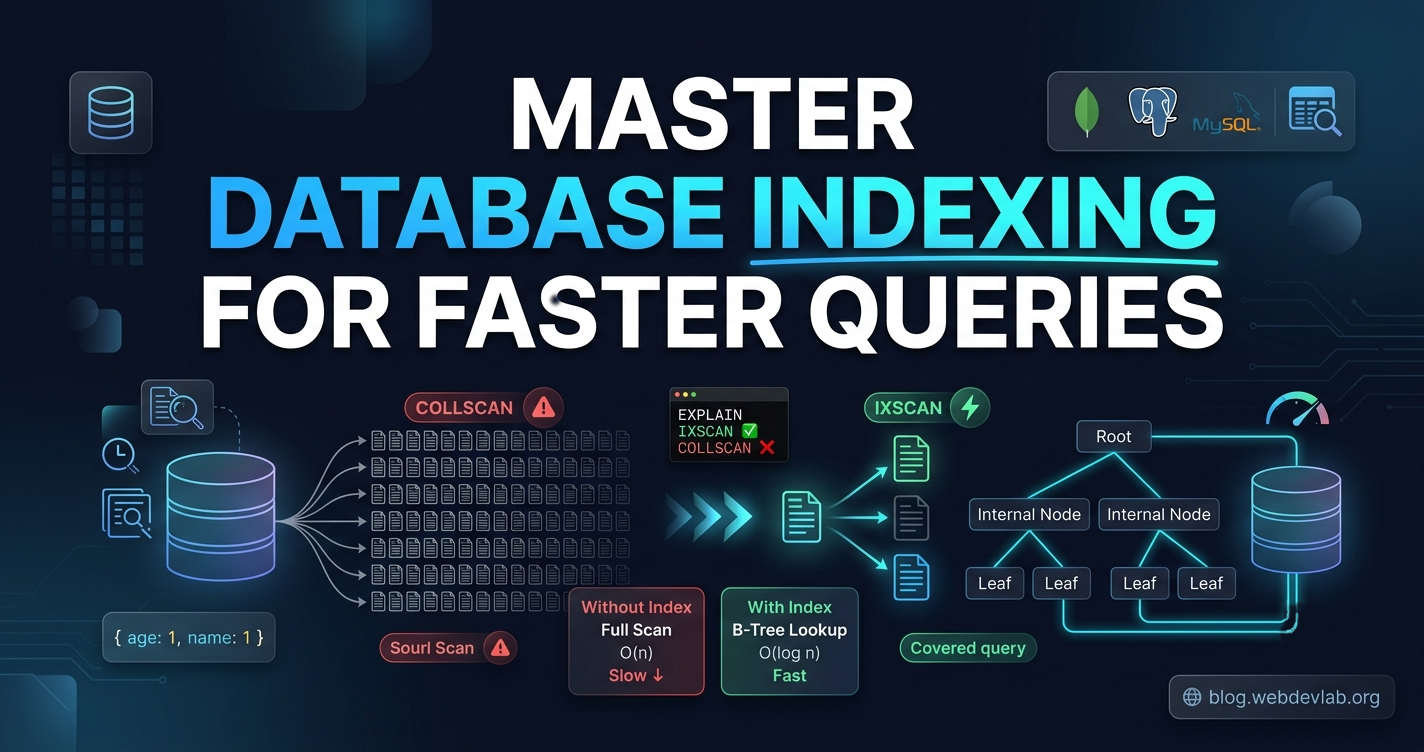
No index (COLLSCAN): the database reads every document, one at a time. Time complexity is O(n). Double the data, double the time.
With an index (IXSCAN): the database walks a B-Tree. Time complexity is O(log n). Double the data, add one step.
Now think about a billion documents. A linear scan checks around 500 million docs on average. An index lookup finds the value in about 30 steps.
That's not an optimization. That's the difference between a working app and a frozen one.
Indexes help with sorting too. Without one, MongoDB loads every matching doc into memory to sort it. And if the sort goes over 32MB, it fails. An index returns results already sorted, so that bottleneck just goes away.
Read article on "From SQL to MongoDB"
Your First Index: A Quick Example
Let's make it concrete. Say you have a products collection with 500,000 docs.
javascript
db.products.find({ sku: "XJ-99-BLK" })Step 1: Check the explain plan.
javascript
db.products.find({ sku: "XJ-99-BLK" }).explain("executionStats")You'll see "stage": "COLLSCAN" and "totalDocsExamined": 500000. It's reading every doc. That's a red flag in any database.
Step 2: Create the index.
javascript
db.products.createIndex({ sku: 1 })Step 3: Run explain again.
javascript
db.products.find({ sku: "XJ-99-BLK" }).explain("executionStats")Now you'll see "stage": "IXSCAN", "totalDocsExamined": 1, and "totalKeysExamined": 1. Way faster.
Read article on: "Choose Between FastAPI and Express.js in 2026"
Compound Indexes: The Multi-Level Card Catalog
Single-field indexes are easy. But what if your query filters by city and sorts by age?
javascript
db.users.find({ city: "Portland" }).sort({ age: 1 })Making two separate indexes, one on city, one on age, is a common mistake. The database will usually use just one to find docs. Then it does a slow in-memory sort for the rest.
A compound index fixes this. Think of a phone book sorted by city, then by last name within each city.
javascript
db.users.createIndex({ city: 1, age: 1 })Inside, the B-Tree looks like this:
text
[Austin, 22] -> [Austin, 25] -> [Austin, 30] -> [Boise, 21] -> [Boise, 22] -> [Portland, 19] -> [Portland, 24] -> [Portland, 27]Sorted by city first. Then by age within each city. The database finds the "Portland" block and streams results back in perfect age order. No extra sorting needed.
Postgres does the same thing. A composite B-Tree index on (city, age) gives you identical behavior.
Article on: "Chose Between Driver and Mongoose for MongoDB CRUD"
The Golden Rule: Index Prefixes and the ESR Rule
An index on { city: 1, age: 1, name: 1 } supports queries on these prefixes:
{ city: 1 }{ city: 1, age: 1 }{ city: 1, age: 1, name: 1 }
It does not work well for a query on { age: 1 } alone. Why? Because the B-Tree sorts by city first. Without filtering on city, the age entries are spread all over. The database has to scan every leaf node.
Think of a phone book indexed on {last_name, first_name}. Finding everyone named "Alex" means reading the entire book. The first key in a compound index is your entry gate.
The ESR Rule
This is one of the most important rules for compound indexes. When you're designing for Equality, Sort, and Range, the key order matters a lot.
Equality first, sort second, range last.
javascript
db.orders.find({
  user_id: "u123",
  order_date: { $gte: ISODate("2023-01-01") }
}).sort({
  total_amount: -1
})
The right index:
javascript
db.orders.createIndex({ user_id: 1, total_amount: -1, order_date: 1 })Why is total_amount (sort) before order_date (range)?
Once you hit a range query ($gte, $lte, $ne) on a key, the index stops being useful for sorting by later keys. Put the sort key before the range key, and results for user_id: "u123" come back perfectly sorted by total_amount. Then the range filter on order_date kicks in.
Index Cardinality: Targeting the Needle in the Haystack
Cardinality just means the number of unique values in an index. High cardinality: email. Low cardinality: is_active (true/false), gender.
Databases are cost-based optimizers. They estimate whether an index is cheaper than a full scan. For a really low-cardinality field, an index scan can actually be slower.
Picture an index on gender with a million docs, split 50/50.
IXSCAN: the index finds 500,000 pointers. The database then chases each one to grab the full doc from random disk locations. That's chaotic I/O. Super slow.
COLLSCAN: a full scan reads data in order, in big blocks. For large result sets, it's often twice as fast.
The fix? Compound indexes. Pairing { gender: 1, last_login: -1 } gives you high cardinality and makes the index useful for "last 10 active male users."
Covered Queries: The Ultimate Performance Hack
A covered query is the holy grail of read performance. It's "covered" when every field the query needs is inside the index itself. The database answers the query entirely from the index. No disk access to documents.
Under heavy load, that's the difference between 2ms and basically 0ms.
javascript
db.users.find(
  { city: "Portland", age: { $gt: 25 } },
  { name: 1, age: 1, city: 1, _id: 0 }
)

db.users.createIndex({ city: 1, age: 1, name: 1 })
In explain(), you'll see "totalDocsExamined": 0. Everything came from the index.
One catch: in MongoDB, a covered query is impossible if _id is returned, and it is by default. You have to project it out with _id: 0.
Specialized Indexes for Special Problems
Beyond standard B-Trees, MongoDB has some specialized indexes that solve specific problems nicely.
TTL Indexes: Documents with an Expiration Date
A TTL (Time-To-Live) index automatically deletes documents after a set number of seconds. Perfect for sessions, short-lived tokens, machine-generated logs, anything that goes stale after a while.
A background thread runs every 60 seconds, scans the TTL index for expired dates, and removes those docs.
javascript
db.session_logs.createIndex(
  { "createdAt": 1 },
  { expireAfterSeconds: 3600 }
)
Important: the indexed field has to be a BSON date or an array of dates. TTL indexes can't be compound, but they can be partial.
Sparse Indexes: Saving Space on Missing Fields
By default, an index has an entry for every doc. If the indexed field is missing, it inserts a null key. A sparse index only indexes docs that actually have the field.
javascript
db.users.createIndex(
  { phone_number: 1 },
  { sparse: true }
)
Smaller and faster if phone_number is rare. But watch out: a sparse index on { x: 1 } won't be used for a { x: null } query, because it doesn't have entries for docs where x is missing.
Partial Indexes: An Unfair Advantage
A partial index uses a filter expression to index only some docs. It's different from sparse, this is an explicit rule for what gets included. You get the smallest, fastest index possible for a specific query pattern.
javascript
db.orders.createIndex(
  { customer_id: 1, order_date: -1 },
  {
    partialFilterExpression: {
      status: "pending",
      total: { $gt: 500 }
    }
  }
)
This index ignores 95% of the orders collection. It's tiny, stays in RAM, and it's crazy fast. The query planner will only use it if your query logically includes the partialFilterExpression.
Text Search Indexes: Built-In Search
A text index tokenizes and stems string content for full-text search. It handles "runs," "running," and "ran" automatically. Simpler than spinning up Elasticsearch for basic stuff.
javascript
db.blog_posts.createIndex(
  { title: "text", body: "text", tags: "text" },
  { weights: { title: 10, tags: 5 } }
)

db.blog_posts.find(
  { $text: { $search: "mongodb indexing" } },
  { score: { $meta: "textScore" } }
).sort({ score: { $meta: "textScore" } })
Limitation: a collection can only have one text index, and building it can be expensive. Great tool, but not a replacement for real search at scale.
When NOT to Use an Index
Indexing isn't free. It's a space-for-time trade-off with three real costs.
1. Writes get slower. Every INSERT, UPDATE, or DELETE has to update the collection and every relevant index's B-Tree. An index on a heavily updated field like last_seen_at can tank your write throughput.
2. Memory goes up. For peak performance, your active working set should fit in RAM. A server with 16GB of RAM might cache a 10GB collection perfectly, but add 6GB of useless indexes and you get disk thrashing. Performance falls off a cliff.
3. Storage costs. Indexes take disk space. A 10GB collection can easily have 3-5GB of indexes. Redundant indexes just multiply the waste.
When to skip the index:
Very small collections (under 1,000 docs).
Fields with really low cardinality, unless they're part of a compound index.
Write-heavy, read-light tables (raw clickstream logs, for example).
Queries you run once a month.
Common Indexing Mistakes and Anti-Patterns
I see these in production code reviews all the time.
The shotgun approach. Making an index on every field. Worst mistake you can make. You destroy writes, waste RAM, and confuse the optimizer.
Redundant indexes. Having { a: 1 } and { a: 1, b: 1 }. The first one is redundant, any query using it can use the prefix of the second. Drop { a: 1 }.
Ignoring sort order in compounds. Making { a: 1, b: 1 } for a query that sorts by b descending. That index can't be used for the sort. The right one is { a: 1, b: -1 }.
The negation trap. Queries with $ne, $nin, or $not often don't use indexes well. The database has to scan the non-matching part of the index, which can be huge. Reframe your logic when you can.
Case-insensitive regex without a plan. A query for { name: /alex/i } can't use a standard index. Store a lowercased version of the field in a separate, indexed field.
Best Practices and a Real-World Optimization Walkthrough
Let's optimize a slow admin panel query in an e-commerce app.
The slow query: an admin wants all "shipped" orders from Chicago in the last quarter, sorted by customer name. Showing order ID, total, and date.
javascript
db.orders.find({
  city: "Chicago",
  status: "shipped",
  order_date: {
    $gte: ISODate("2023-10-01"),
    $lt: ISODate("2024-01-01")
  }
}).sort({
  customer_name: 1
})
Step 1: Apply ESR.
Equality:
city,statusSort:
customer_nameRange:
order_date
Step 2: Build the optimal index.
javascript
db.orders.createIndex({
  city: 1,
  status: 1,
  customer_name: 1,
  order_date: 1
})
Step 3: Make it covered.
The query only needs _id, total, date, and customer_name. Add total to the index, and project _id away.
javascript
db.orders.createIndex({
  city: 1,
  status: 1,
  customer_name: 1,
  order_date: 1,
  total: 1
})

db.orders.find({
  city: "Chicago",
  status: "shipped",
  order_date: {
    $gte: ISODate("2023-10-01"),
    $lt: ISODate("2024-01-01")
  }
}, {
  customer_name: 1,
  order_date: 1,
  total: 1,
  _id: 0
}).sort({
  customer_name: 1
})
Now explain("executionStats") shows "totalDocsExamined": 0 and "totalKeysExamined" matching nReturned. The query is as fast as it can be. Almost no load on the database.
Frequently Asked Questions
How many indexes is too many?
No hard number. But for a heavily updated collection, 5-7 is a good ceiling. Audit them every so often, MongoDB's $indexStats shows which indexes haven't been used in weeks and are safe to drop.
Can I create an index while the app is running?
Yes, but do it safely. In older MongoDB versions, foreground index builds block all reads and writes. Build in the background (it's the default in recent versions, but be explicit) and watch replica set lag during the process.
Why isn't my query using the new index?
The planner sees it, but chose something else, another index, or a full collection scan. This happens when cardinality is terrible or when the query uses a wildcard regex like /$something/. Check the rejectedPlans section of explain().
What's a multikey index?
When you index a field holding an array, MongoDB automatically makes a multikey index with one entry per array element. Powerful, but there's a rule: a compound index can only have one multikey field. Two array fields in a single compound index throws an error.
Conclusion and Next Steps
Database indexing isn't a dark art. It's just disciplined engineering. You've moved past "index equals speed" into B-Tree mechanics, compound key ordering, and the real power of covered queries. Going from a 30-second timeout to a 0.0ms covered query is one of the best wins in backend work.
You don't become an indexing expert overnight. You build the muscle by reading explain plans, questioning every COLLSCAN, and gently interrogating your database about its decisions.
Practical next steps:
Run
explainon a slow endpoint today. Find a COLLSCAN. Build a targeted index. Watch it disappear.Audit your indexes. Use
$indexStatsto spot redundancy and drop what's just overhead.Design indexes before writing the next feature, model the queries first.
For deeper practice, check out MongoDB's Performance Advisor in Atlas. It flags slow queries and suggests indexes. If you're on Postgres, learning to read EXPLAIN ANALYZE output is the equivalent next step.